Hi,
I am currently working on a Liberty Create API function that allows an external system to retrieve some data.
We are using Liberty Create 2025.3.
The API works correctly in our build/test environment, which contains approximately 600 records. However, in the live environment, where the underlying object contains hundreds of thousands of records, the request runs for around 60 seconds before returning a 500 Internal Server Error.
At present, the API function returns data from an object using an inline response template. I have implemented a response postprocessor that performs pagination after the data has been retrieved.
My understanding now is that this processing occurs too late in the execution flow. The API appears to retrieve and serialise the entire dataset before the postprocessor applies the slice() operation, resulting in significant performance issues in the live environment.
Questions
What is the recommended approach for implementing efficient server-side pagination in a Liberty Create API function?
Specifically:
- Can the
startNumber and numberToReturn query parameters be passed directly into the underlying search or inline data source?
- Is there a supported Liberty Create configuration for query-level pagination, including:
- Page size / limit
- Offset / starting row
- Cursor or continuation-token based paging
- Stable sorting to ensure consistent page results
In addition:
- Where is the underlying search or data retrieval logic configured when data is exposed through an inline object response?
- Is there a recommended pagination pattern for handling large API responses in Liberty Create 2025.3?
- If server-side pagination is not supported for inline object responses, what is the recommended design pattern for exposing large datasets from a Liberty Create application to third-party APIs?
The desired behaviour is that a request causes the underlying query to retrieve only x records from the data source, rather than retrieving hundreds of thousands of records and reducing the result set afterwards.
Any guidance on the correct configuration or supported implementation approach would be greatly appreciated.
Thanks.
Hi,
The short answer is unfortunately no, there is no native support for paginated API results. Every request is handled independently and returns full results.
A processor may be able to provide a solution after the fact, but if you are already hitting an issue with the size of data prior to this, then as you have found this probably won’t help.
Another consideration is that even if you did implement pagination this way, there is no guarantee that records won’t change between subsequent requests, potentially leading to retrieving duplicate records, or even missing some records.
Regards the 500 error, you can raise a support request ( Support - Netcall Community ) to try and find out more about what the actual issue is, although from your description it sounds like it might be running out of memory. If so, you can increase the memory allocation in System Variables, but given the duration of your request it may be better to look at other ways of reducing the scope of what is returned.
Is there any other field you could search by, allowing fetching of results in smaller chunks? Maybe some sort of category or other grouping that would reduce each request to just a portion of the total results.
The Date Created field might be a good example, if your records are created over a wide period of time, you could try limiting each API request to just a specific week/month/year etc. And then iterate through those with each subsequent requests, giving you pseudo-pagination. Also the Date Created field won’t change, so much safer to prevent duplicate/missing records.
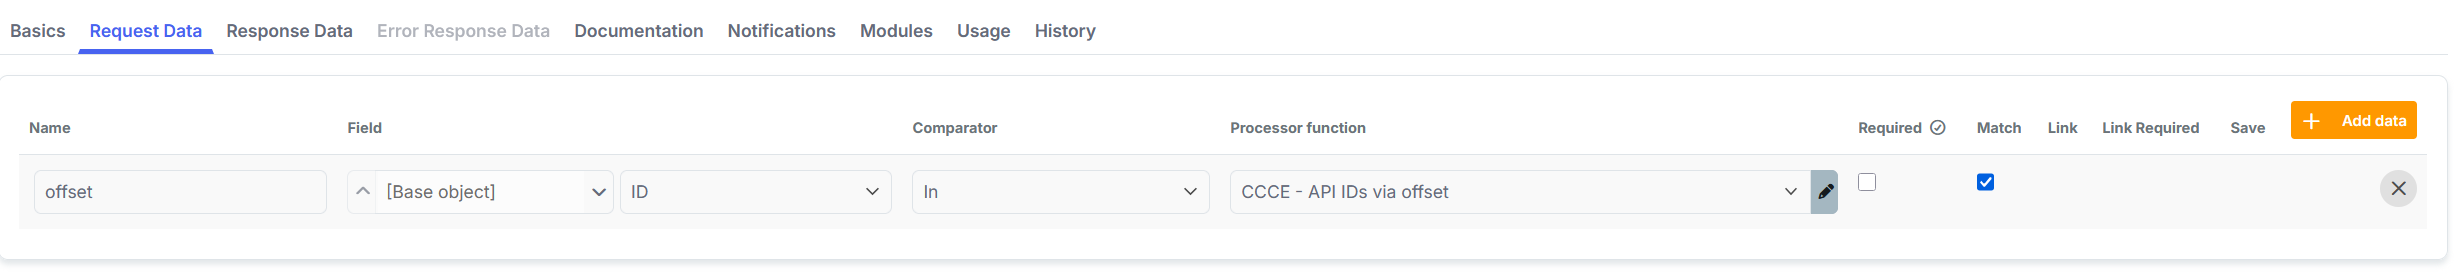
I managed to do something like this by included a request variable that internally was a list of IDs for records to provide in the response, but was portrayed externally as an offset. I then had a data processors on the line that ran a cs.search to pull back a list of IDs with a fixed limit of 1000 records and return this as part of the response. I hadn’t though about the possibility of returning duplicates so might need to add an order parameter to the search, and even then it probably wouldn’t be perfect. In theory the same trick (internally asking for one thing whilst externally asking for another and using a request field processor to translate) could be used to request 2 input fields and possibly to provide a count of records returned on the ouitput.
/**
 * Field Processor
 * Processes individual columns within a set of data, typically within
 * imports/exports and API calls/handlers
 */
return {
	/**
	 *
	 * @param {string} input The value to be processed
	 * @param {Object} params Additional context parameters
	 *
	 * @returns {string} The processed value
	 */
	main: function (input, params) {
		cs.log(`CCCE - API IDs via offset`)
		cs.log(`input=${input}`)
		cs.log(`params:`)
		cs.log(params)
		let api_ids = []
		if (input) {
			api_ids = cs.search({
				'base_object_id': cs.ref('object_case'),
				'selects': {
					id: ':id',
				},
				'filters': [{ 'field_path': cs.ref('field_case_subset_ccceCASECaseTypeLCCFeedbackFormComplete'), 'comparator': 'equal_to', 'value': 1 }],
				'limit': input + ',1000',
				'return': 'column'
			});
		} else {
			api_ids = cs.search({
				'base_object_id': cs.ref('object_case'),
				'selects': {
					id: ':id',
				},
				'filters': [{ 'field_path': cs.ref('field_case_subset_ccceCASECaseTypeLCCFeedbackFormComplete'), 'comparator': 'equal_to', 'value': 1 }],
				'return': 'column'
			});
		}
		cs.log(`api_ids:`)
		cs.log(api_ids)
		return api_ids
	}
}